
باحثون من برينستون وآنت جروب وستانفورد يقدمون AQuA: إطار عمل وكيل من جزأين لاكتشاف العوامل المستقلة وتطوير النماذج في التمويل الكمي
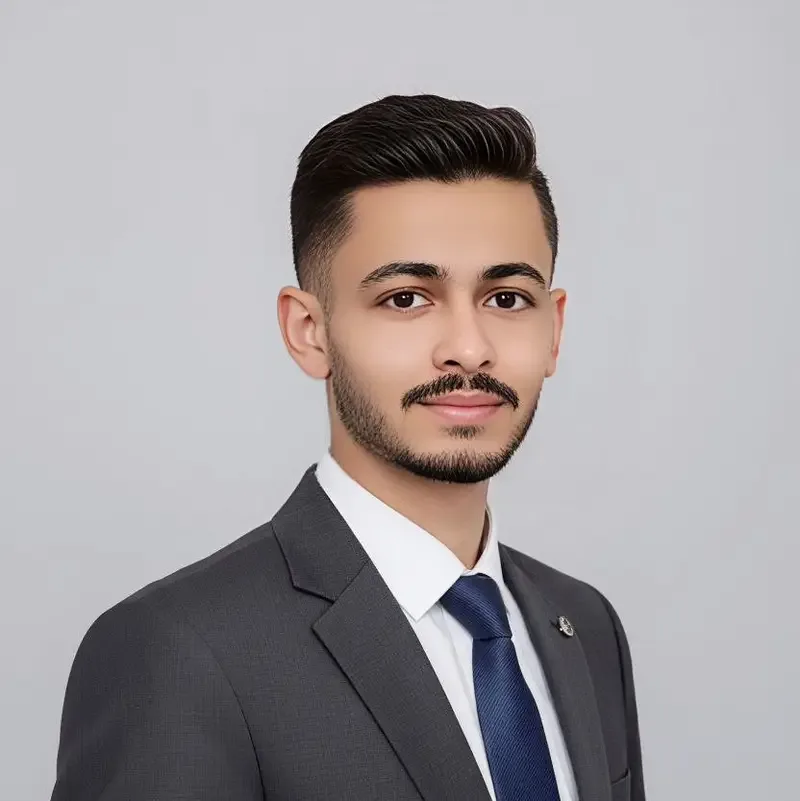
قامت برينستون وآنت جروب وستانفورد ببناء AQuA، وهما وكيلان للأبحاث الكمية ذاتية التحسين، حيث يجعل صندوق الحماية المحكم تسرب البيانات غير قابل للكتابة
استخدام lovable unlimited بدون حدود
أعرف المزيدعندما يصمم وكلاء البحث الكمي تجاربهم الخاصة، فقد يلوثون الأدلة المستخدمة لتوجيه العمل اللاحق.
يمكن تسجيل ميزة عالية الدرجات مع تسرب البيانات كمثال ناجح ونقلها إلى التكرارات المستقبلية. لا القواعد المستندة إلى السرعة ولا وكلاء المراجعين يزيلون هذا الخطر، حيث يمكن أن يكون لدى مؤلف التجربة والمراجع نقاط عمياء متطابقة. يقدم الباحثون في جامعة برينستون ومجموعة آنت وجامعة ستانفورد أكوا. يشتمل AQuA على نظامين بحثيين يعتمدان على نموذج اللغة ويعملان على تحسين سير عمل البحث الخاص بهما عبر التكرارات المتعاقبة بينما تظل آليات التقييم الخاصة بهما ثابتة. البحث الأول عن عوامل ألفا الرمزية في أسواق العملات المشفرة؛ والثاني يبني نماذج السلاسل الزمنية للأسهم الأمريكية. تعمل الأنظمة بشكل مستقل، ولا تتشارك أي عوامل أو ذكريات أو مساحات مرشحة أو حالة بحثية.
يعالج الفشل المنهجي AQuA
وحتى الأخطاء المنهجية البسيطة يمكن أن تقوض البحث الكمي، مما يؤدي إلى اختبارات خلفية تبدو مقنعة ولكن لا يمكن إعادة إنتاجها - وهي مشكلة موثقة منذ زمن بعيد مثل بيلي وآخرين. إن السماح للوكيل بتأليف تجاربه الخاصة يزيد من الخطر: إذا كانت الميزة المتأثرة بالتسرب تؤدي أداءً جيدًا، فقد تصبح سابقة مخزنة. يمكن للتكرار العودي بعد ذلك تعزيز العيب غير الملحوظ بنفس السهولة التي يتم بها اكتشاف حقيقي.
لا توفر التعليمات السريعة والمراجعة المستندة إلى النموذج حدود نزاهة موثوقة. تؤدي إعادة استخدام موقع ثابت بشكل متكرر إلى التجهيز الزائد التكيفي، وقد لوحظ أن وكلاء LLM يستغلون أهدافًا ومقيمين محددين بشكل خاطئ. تتخذ AQuA نهجًا مختلفًا من خلال منع الإجراءات التي قد تؤدي إلى التسرب. قبل بدء التكرار، يقوم كل نظام بتأمين تقسيمات البيانات الخاصة به وتعريفات الميزات والتسميات والمقيم. يمكن للوكيل إخراج تعبير عامل مقيد فقط أو فرق تكوين واحد فقط. يستخدم هذا التصميم حرية غير متكافئة: يظل الاستكشاف مرنًا داخل DSL الخاص بالوكيل، بينما يظل المُقيِّم خارج السطح التكيفي. إن سير العمل في البحث، وليس آلية التحكيم، هو ما يتطور.
شرح تفاعلي
الجزء الأول: اكتشاف العامل المنسق من قبل المدير
ينظم الجزء الأول ستة وكلاء - مشرف البيانات، والمحلل البصري، وعامل منجم الأفكار، ومقيم العوامل، ومهندس الاختبار الخلفي، وأمين مكتبة الأبحاث - في مسار يشرف عليه مدير الذكاء الاصطناعي. لا يُسمح بإجراء مكالمات مباشرة من وكيل إلى وكيل. وبدلاً من ذلك، يتعامل المدير مع كل عملية تسليم، مع الحفاظ على إمكانية تدقيق كل عملية تشغيل.
يبدأ كل عامل باقتراح قابل للدحض وليس بتعبير جاهز. ويحدد الاقتراح فرضية وآلية واتجاها متوقعا وشروطا تدحضه. بعد ذلك فقط يتم إنشاء العامل باستخدام سجل مشغل صيغة ألفا القياسي. يصل مشغلو السلاسل الزمنية إلى النوافذ اللاحقة حصريًا، بينما يستخدم مشغلو المقطع العرضي الطابع الزمني الحالي فقط؛ وبالتالي فإن تكوين هذه العوامل يحافظ على السببية. تعمل الملاحظات من خلال ثلاث حلقات: معايرة الاتجاه ضمن الاختبار الخلفي، ومراجعة الاعتقاد المدفوعة بالتزييف أثناء التشغيل، والذاكرة المحمولة عبر عمليات التشغيل لتوجيه البحث التالي.
في عالم العملات المشفرة الذي مدته خمس دقائق، يتسلق التحقق المشترك لـ Spearman IC عبر 20 حقبة بحثية إلى ما يقرب من 0.190، مقابل 0.171 للتكيف AlphaMemo، 0.151 للتكيف ألفا جين، 0.137 لـ LSTM، 0.106 لـ LightGBM و 0.075 لخط الأساس على نمط Alpha158. تظل الآليات الفردية ضعيفة، حيث تتراوح قيمة المرحلية الفردية من 0.026 إلى 0.037. المطالبة تتعلق بالحزام، وليس بتعبير واحد.
الجزء الثاني: تطوير النموذج المعتمد على التكوين
يتنبأ الجزء الثاني بالعائد الآجل لكل سهم خلال الثلاثين دقيقة القادمة على الأسهم الأمريكية خلال اليوم. يستمر التدريب في الفترة 2010-2019، و2020 عبارة عن فجوة حظر لا يمسها شيء، و2021-2025 عبارة عن بيانات اختبار لم تمسها. يستخدم التحديد شريحة التحقق الداخلي من نهاية نافذة التدريب فقط.
الفرضية هنا هي اختلاف تكوين واحد - البنية أو الخسارة أو أخذ العينات أو المحسن - وينتج اختلاف واحد متغيرًا واحدًا بالضبط، مع الحفاظ على المتغيرات قابلة للمقارنة. المتنبئ عبارة عن هجين: واجهة أمامية تلافيفية متعددة النطاق أحادية الأبعاد، وعمود فقري قابل للتكوين يمتد على LSTM، مامبا و انتباه (الانتباه في التشغيل المبلغ عنه)، وهي مرحلة مستعرضة تمزج عبر اللوحة، وبوابات الانصهار وقراءات مجمعة لكل مخزون.
لا توجد ميزة واحدة لحجم السعر تحمل الإشارة: الأقوى هو عودة لمدة 5 دقائق عند −0.031، وتصل مجموعة التلال إلى +0.025 فقط. عبر عائلات النماذج التي تحتوي على بيانات متطابقة ونفس المقيِّم، يعمل IC الخام لكل مخزون +0.0251 (التلال)، +0.0397 (LGB)، +0.0434 (xLSTM)، +0.0535 (LSTM)، +0.0613 (GRU) و +0.0843 للهجين - +0.0230 مطلق على أفضل خط أساس، 37.5% نسبي. تستخدم الدوائر المتكاملة المكونة من جزأين اصطلاحات مختلفة وتنص الورقة بوضوح على أنه لا ينبغي مقارنتها.
من الإشارة إلى الإستراتيجية
تصبح النتيجة لكل سهم عتبة محايدة للدولار طويل / قصير بتكلفة ثنائية تبلغ 2 نقطة أساس. يؤدي تحييد القطاع إلى رفع مستوى Sharpe المتوقف إلى +2.15، مع التدريب والقيم المحتفظ بها متساوية تقريبًا. تراكب استهداف التقلبات السببية يرفعه إلى +2.50، ولا يزال هناك تقدم سببي تمامًا في اختيار كل معلمة من البيانات السابقة وحدها +2.00. لكل سهم R² هو 1.20%. يعمل Sharpe حسب العام +1.7 و+3.5 و+1.9 و+1.8 و+2.7 لعام 2021 حتى عام 2025 - وهو إيجابي في كل عام، بما في ذلك السحب في عام 2022.
الوجبات السريعة الرئيسية
- حلقتان بحثيتان مستقلتان: اكتشاف العوامل وتطوير النماذج، ولا تتشاركان أي عوامل أو ذاكرة أو حالة.
- الحرية غير متماثلة: يستكشف الوكيل داخل DSL، ولكن يتم إغلاق الانقسامات والميزات والعلامات والمقيم.
- يصل الجزء الأول إلى ~0.190 IC مدمجًا على العملات المشفرة؛ يصل الجزء الثاني إلى +0.0843 لكل سهم IC مقابل +0.0613 لـ GRU.
- يحمل دفتر الأسهم +2.50 شارب عند 2 نقطة أساس وهو إيجابي في جميع السنوات الخمس، 2021-2025.
When quantitative research agents design their own experiments, they can contaminate the evidence used to guide subsequent work. A high-scoring feature with data leakage may be recorded as a successful example and carried into future iterations. Neither prompt-based rules nor reviewer agents eliminate this risk, since the experiment author and reviewer can have identical blind spots. Researchers at Princeton University, Ant Group and Stanford University introduce AQuA. AQuA comprises two language-model-driven research systems that refine their research workflows over successive iterations while their evaluation mechanisms remain fixed. The first searches for symbolic alpha factors in crypto markets; the second builds time-series models for US equities. The systems operate independently, sharing no agents, memories, candidate spaces or research state.
The methodological failure AQuA addresses
Even minor methodological mistakes can undermine quantitative research, yielding backtests that look persuasive but cannot be reproduced—a problem documented as far back as Bailey et al. Allowing an agent to author its own experiments compounds the danger: if a feature affected by leakage performs well, it can become a stored precedent. Recursive iteration can then reinforce an unnoticed defect just as easily as a genuine finding.
Prompt instructions and model-based review do not provide a reliable integrity boundary. Reusing a fixed holdout repeatedly leads to adaptive overfitting, and LLM agents have been observed exploiting misspecified objectives and evaluators. AQuA takes a different approach by preventing actions that could introduce leakage. Before iteration begins, each system locks its data splits, feature and label definitions, and evaluator. The agent can output only a constrained factor expression or one configuration diff. This design uses asymmetric freedom: exploration remains flexible within the agent’s DSL, while the evaluator stays outside the adaptive surface. The research workflow, rather than its judging mechanism, is what evolves.
Interactive explainer
Part I: Factor Discovery Coordinated by a Manager
Part I organizes six agents—Data Steward, Visual Analyst, Idea Miner, Factor Evaluator, Backtest Engineer and Research Librarian—into a pipeline overseen by an AI Manager. Direct agent-to-agent calls are not permitted. Instead, the Manager handles every handoff, preserving the auditability of each run.
Each factor starts with a falsifiable proposal rather than a ready-made expression. The proposal specifies a hypothesis, a mechanism, an expected direction and conditions that would refute it. Only afterward is the factor constructed using the standard formulaic-alpha operator registry. Time-series operators access trailing windows exclusively, while cross-sectional operators use only the current timestamp; composing these operators therefore preserves causality. Feedback operates through three loops: direction calibration within a backtest, belief revision driven by falsification within a run, and memory carried across runs to guide the next search.
On a crypto five-minute universe the combined validation Spearman IC climbs across 20 research epochs to approximately 0.190, against 0.171 for an adapted AlphaMemo, 0.151 for an adapted AlphaGen, 0.137 for LSTM, 0.106 for LightGBM and 0.075 for an Alpha158-style baseline. Individual mechanisms stay weak — single-factor ICs of 0.026 to 0.037. The claim is about the harness, not one expression.
Part II: Config-Driven Model Development
Part II predicts each stock’s forward return over the next thirty minutes on intraday US equities. Training runs on 2010–2019, 2020 is an embargo gap nothing touches, and 2021–2025 is untouched test data. Selection uses an inner-validation slice from the end of the training window only.
A hypothesis here is one config diff — architecture, loss, sampler or optimizer — and one diff produces exactly one variant, keeping variants comparable. The predictor is a hybrid: a multi-scale 1-D convolutional front-end, a configurable backbone spanning LSTM, Mamba and attention (attention in the reported run), a cross-sectional stage that mixes across the panel, gated fusion and a pooled per-stock readout.
No single price-volume feature carries the signal: the strongest is a 5-minute return at −0.031, and a ridge combination reaches only +0.025. Across model families on identical data and the same evaluator, per-stock raw IC runs +0.0251 (ridge), +0.0397 (LGB), +0.0434 (xLSTM), +0.0535 (LSTM), +0.0613 (GRU) and +0.0843 for the hybrid — +0.0230 absolute over the best baseline, 37.5% relative. The two parts’ ICs use different conventions and the paper states plainly they should not be compared.
From Signal to Strategy
The per-stock score becomes a dollar-neutral threshold long/short book at a two-leg cost of 2 bps. Sector-neutralizing raises the held-out Sharpe to +2.15, with training and held-out values nearly equal. A causal volatility-targeting overlay lifts it to +2.50, and a fully causal walk-forward choosing every parameter from past data alone still reaches +2.00. Per-stock R² is 1.20%. Sharpe by year runs +1.7, +3.5, +1.9, +1.8 and +2.7 for 2021 through 2025 — positive in every year, including the 2022 drawdown.
Key Takeaways
- Two independent research loops: factor discovery and model development, share no agents, memory or state.
- Freedom is asymmetric: the agent explores inside a DSL, but splits, features, labels and evaluator are sealed.
- Part I hits ~0.190 combined IC on crypto; Part II hits +0.0843 per-stock IC versus +0.0613 for a GRU.
- The equity book holds a +2.50 Sharpe at 2 bps and is positive in all five years, 2021–2025.
Note:Thanks to the Ant Research team for the thought leadership/ Resources for this article. Ant Research team has supported this content/article for promotion.
Asif Razzaq
Website |Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
عبدالرحمن ربيع
Software Engineer & AI Builder
مطور برمجيات متكامل ومصمم جرافيك مع أكثر من 4 سنوات خبرة في بناء تطبيقات الويب الحديثة باستخدام PHP و JavaScript و HTML و CSS. خلفية قوية في تصميم UI/UX واستخدام متقدم لأدوات الذكاء الاصطناعي لتعزيز كفاءة التطوير والأتمتة واتخاذ القرارات. حاصل على ماجستير تنفي...
مقالات ذات صلة
Alibaba Qwen Releases Qwen3.8-Omni-Flash: A 1M-Context Omni-Modal Model Built Around Agentic Audio-Video Understanding and Tool Use
اقرأ المقال
Best Open-Source Agent Harnesses for Local LLMs in 2026
اقرأ المقال
المكدس الفائق: مجموعة بداية Laravel مع فتيلة و NativePHP
اقرأ المقال
التعليقات (0)
كن أول من يعلّق على هذا المقال.